- abstracts analyzed
- 7,087
- name a quantitative method
- 37%
- of method-naming abstracts use panel data
- 19%
Economics has the clearest toolkit in our analysis of 50,799 social science and health dissertation and thesis abstracts: observational data over time, analyzed with methods designed to get closer to cause and effect.
What is in this sample
The most common topics are economic growth and fiscal policy, housing markets, sports analytics, COVID-19 impacts, market volatility, labor markets and wage inequality, taxation, and microfinance. Of the 7,087 abstracts, 37% name a quantitative method, and only 8% describe qualitative work, the lowest share of any field we have analyzed.
The methods these dissertations name most
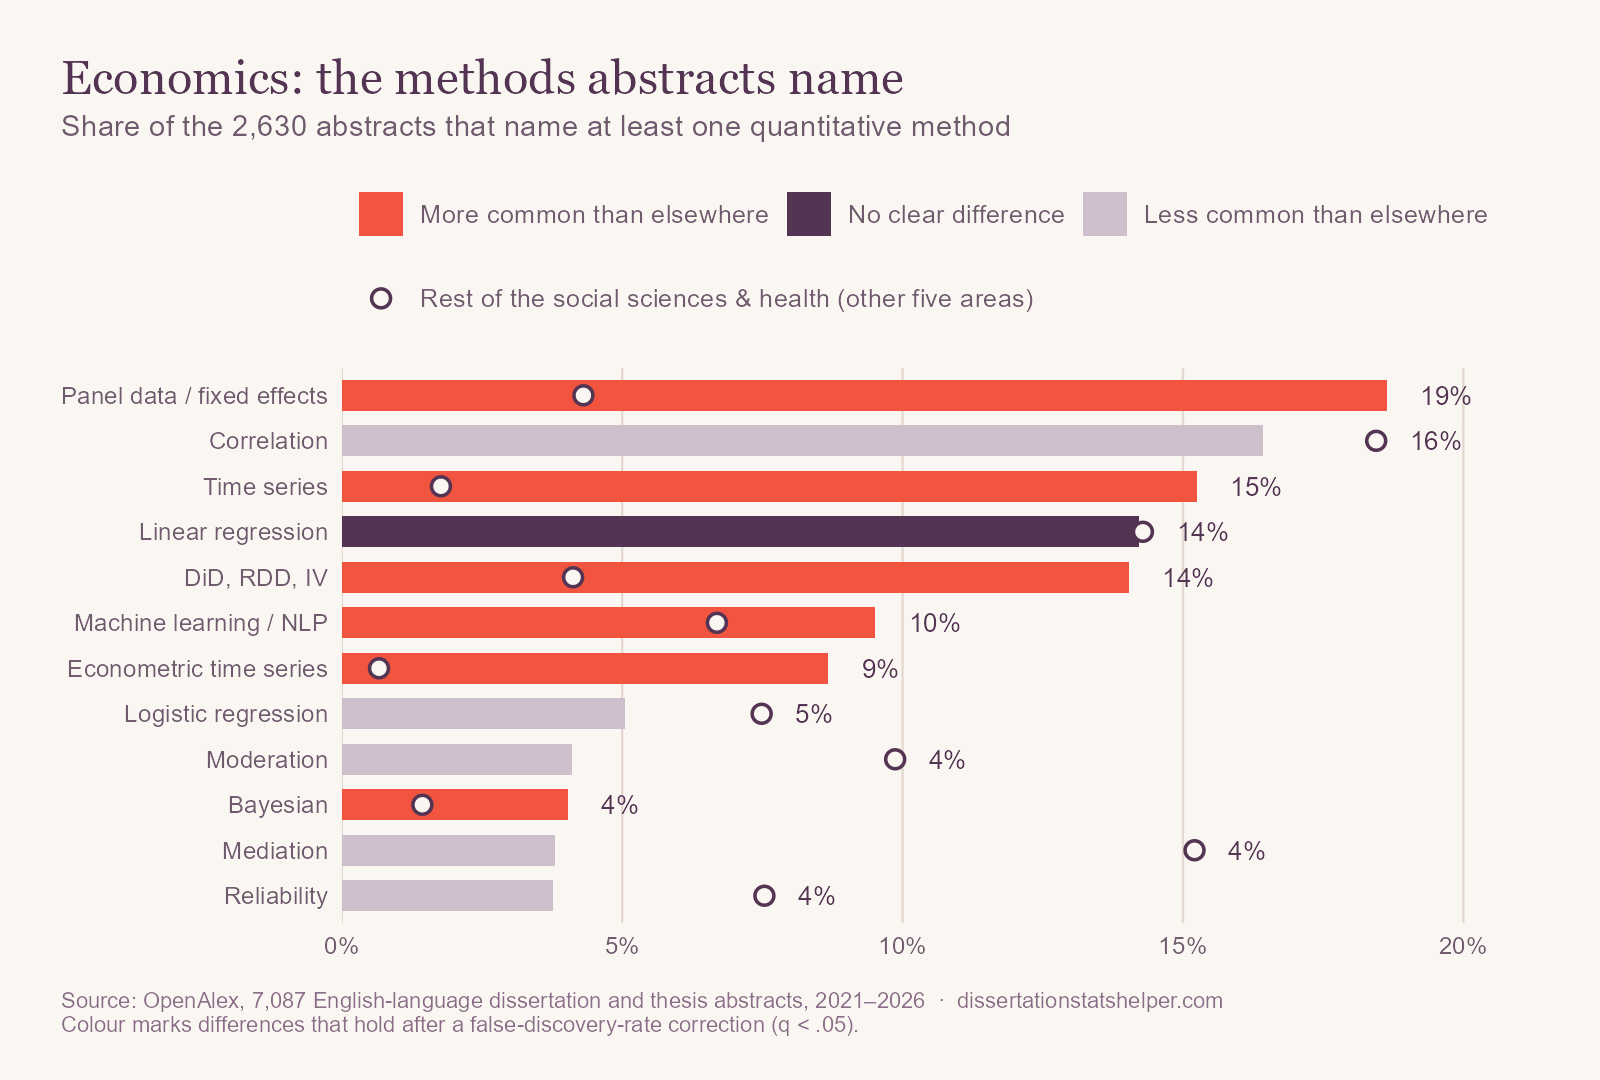
The econometric methods dominate, and all are far more common here than in the other five fields:
- Panel data models (19% vs. 4%): fixed effects, random effects, and GMM for countries, firms, or households over time.
- Time series (15% vs. 2%) and econometric time series such as ARDL, cointegration, and GARCH (9% vs. 1%).
- Causal designs (14% vs. 4%): difference-in-differences, regression discontinuity, instrumental variables, and event studies.
- Machine learning (10% vs. 7%), Bayesian methods (4% vs. 1%), and discrete choice models (3% vs. 2%).
Mediation (4% vs. 15%), moderation (4% vs. 10%), and reliability (4% vs. 8%) are rare.
What changed since 2021
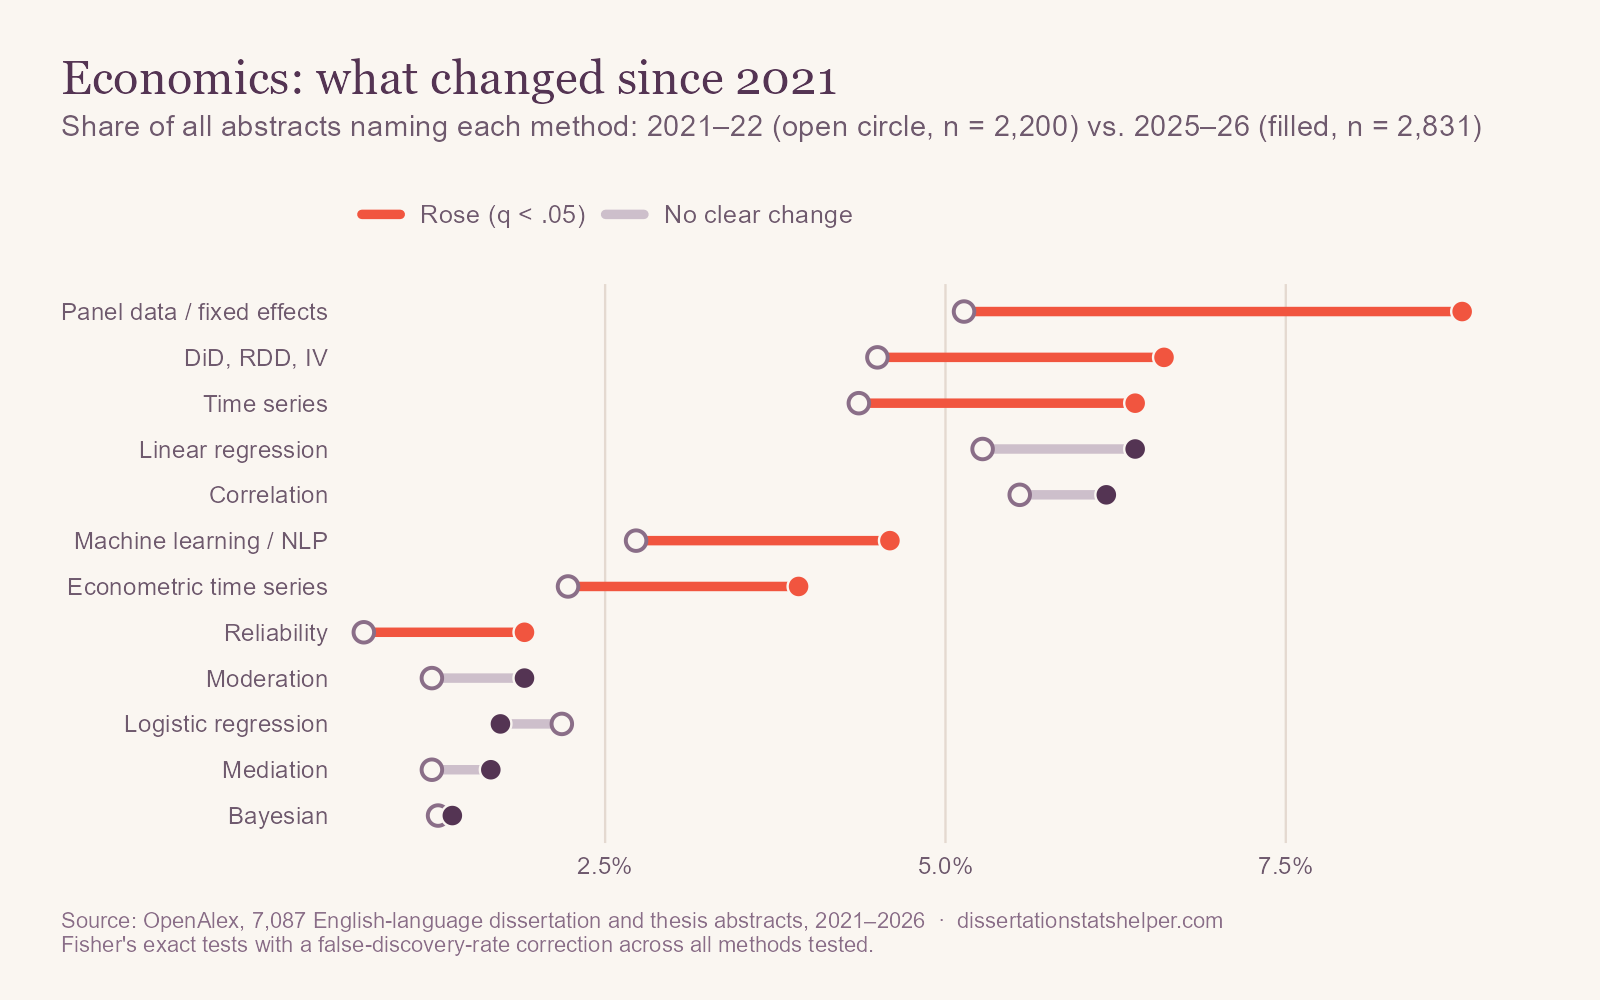
Economics changed more than any other field in this series. The share of abstracts naming a quantitative method rose from 32% to 43%. Panel data models rose from 5.1% to 8.8% of abstracts, causal designs from 4.5% to 6.6%, time series from 4.4% to 6.4%, and machine learning from 2.7% to 4.6%. All survive our correction.
What these abstracts leave out
One of 7,087 abstracts mentions a power analysis, and 13 mention missing data. In applied economics, the unreported decisions are usually about sample construction, standard errors, and which specification is the main one.
If you're planning an economics dissertation or thesis
- Test your identifying assumptions. Show pre-trends for difference-in-differences, first-stage strength for instruments, and continuity around the cutoff for regression discontinuity.
- Cluster standard errors at the right level. Usually the level at which treatment varies.
- Check stationarity first. Unit-root and cointegration tests decide which time-series model is valid.
- Report robustness honestly. Show how results change across reasonable specifications, not just the one that works.
How we did this
We used OpenAlex, an open index of scholarly works, to collect every English-language dissertation and thesis with an abstract published from 2021 through September 2026 in this field, and searched each title and abstract for about 40 statistical methods, including econometric and health methods such as panel models, difference-in-differences, and survival analysis. The data include master's theses and many works from outside the United States, so “dissertations” here is short for all of them. Percentages describe how often abstracts mention a method, not how often it was used. Comparisons use Fisher's exact tests with a false-discovery-rate correction, and OpenAlex's coverage changes over time, so treat trends with some caution. The overview post has the full method and its limitations. The analysis code and result tables are on GitHub.